Both languagesEvery post exists in English and French. The title goes to the English one, [ FR ] to the French.

Writing

Paper reviews and tutorials, 3 so far. The reviews explain the problem a paper set out to solve, its core idea and how the network is built; the tutorials go step by step, with all the code, from setup to the final result.

WeakStrong

Attention(Q, K, V) = softmax(QKTdk) V

[attention, Vaswani et al. 2017, Attention Is All You Need]

Eight terms that cover most of what I work on. Each cell shows how closely two of them are linked in my projects. Deep learning sits in the middle, tied to computer vision, NLP and speech processing, and the last two are tightly linked through my work on Mooré. Data engineering stays close to data science and MLOps. The grid is symmetric, which a real attention map almost never is, so read it as a picture of which ideas go together, not as weights from a trained model.

Paper reviews
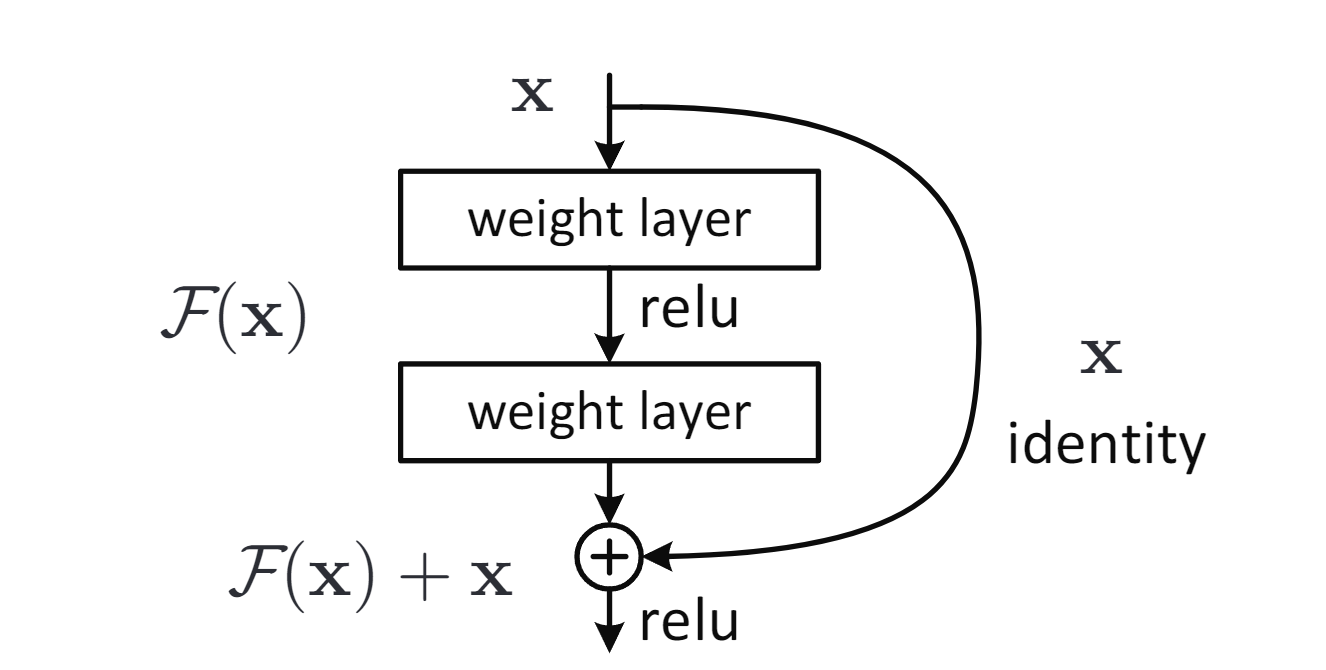
Skip Connexion, a ResNet building block.Tagspaper review · deep learning · cnn · resnet

ResNet, Deep Residual Learning for Image Recognition

EN FR · 7 min read
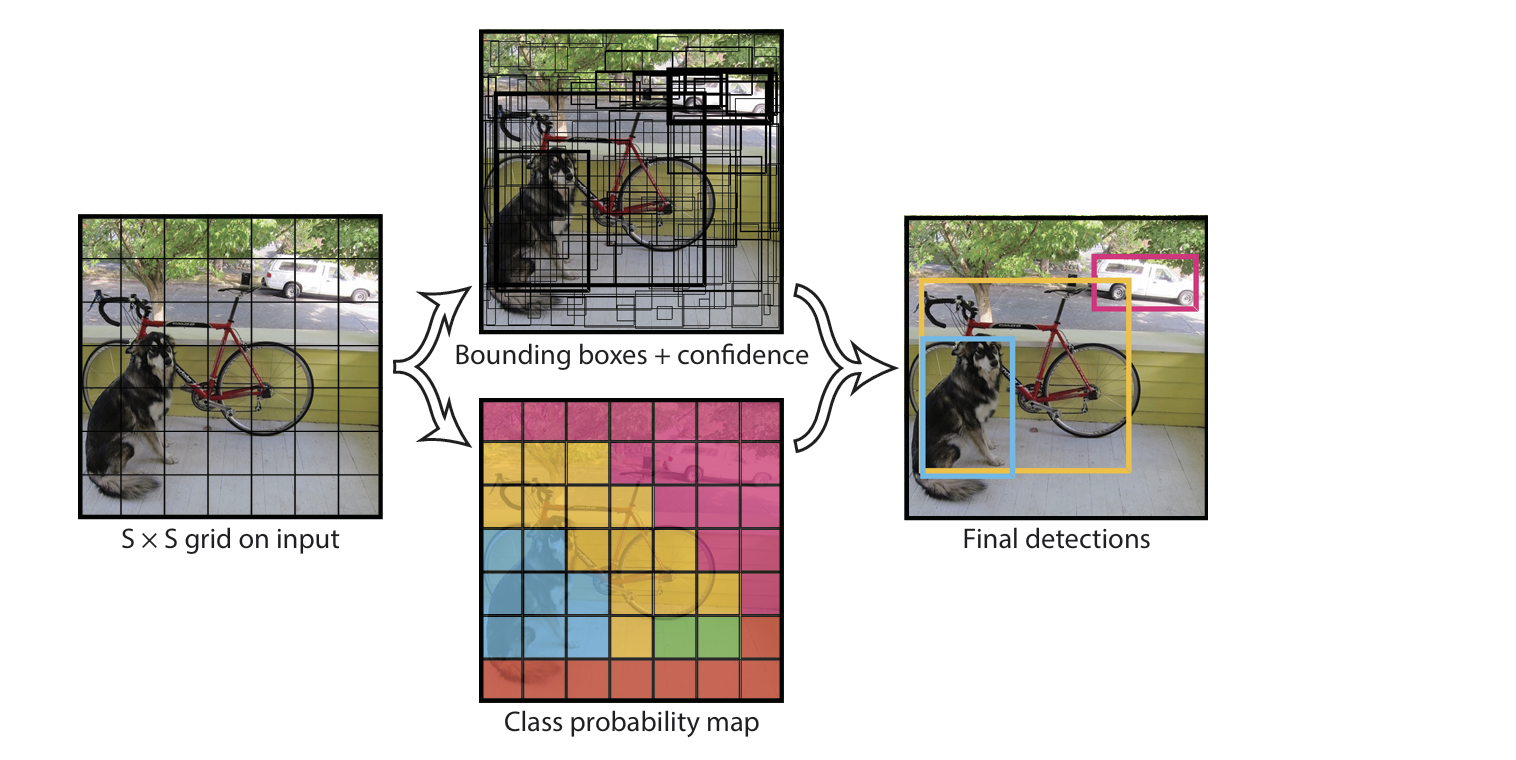
YOLO model.Tagspaper review · deep learning · cnn · yolo

YOLO, You Only Look Once

EN FR · 6 min read

Tutorials

Crawling ProcessTagsmoore · speech recognition · huggingface · tts · asr

MooreSpeechCorpora Toolkit, Collecting Mooré Data from the Bible

EN FR · 4 min read

Colophon

Why these eightA few foundational formulas that power modern deep learning, and that I genuinely find beautiful.

Eight equations, from a single neuron to generative models.

y = φ(∑i wixi + b)

The single unit · Rosenblatt, 1958 · drawn on the work page

f(x) = f(3)(f(2)(f(1)(x)))

Deep feedforward networks · Goodfellow et al., 2016 · drawn on the home page

θ* = arg maxθi log pθ(xi)

Maximum likelihood · after Fisher, 1922

ℒ = − ∑i yi log ŷi

Cross-entropy loss · after Shannon, 1948 · Radio-signal classification

θθηθℒ(θ)

Gradient descent · Cauchy, 1847

y = ℱ(x, {Wi}) + x

Residual block · He et al., 2015 · ResNet, reviewed

Attention(Q, K, V) = softmax(QK / √dk) V

Scaled dot-product attention · Vaswani et al., 2017 · Florence-2 and the VLMs

minθ maxφ 𝔼xpdata[log Dφ(x)] +
𝔼zpz[log(1 − Dφ(Gθ(z)))]

Generative adversarial networks · Goodfellow et al., 2014 · DCGAN on MNIST

Back to the home page →